
PRACTICAL GUIDE FOR SWISS SMEs
A straightforward method for turning hard-to-maintain lists into reliable, reusable data.
| IN BRIEF Structuring your data starts with simple rules. A row represents an event, a column holds one piece of information, and each object has a stable identifier. |
Structure starts with method
Distinguish mandatory rules from preferences. A unique customer ID is essential for linking sales. Column order matters far less. This distinction keeps cleanup manageable and focuses your effort on what changes the result.
Consider missing values. Does a blank cell mean “unknown”, “not applicable” or “not entered yet”? These situations have different implications. We clarify them so a future report can show uncertainty without silently turning it into zero or a default category.
You can organise your data without being a developer. Your business teams already know what an order, customer, invoice or inventory movement means in practice. We turn that knowledge into simple, visible and reusable rules before any tool or code automates the work.
Start with a spreadsheet your teams use every day. Can you explain what each row represents in one sentence? Do you know which columns are mandatory, who corrects errors and which identifier connects this sheet to others? If the answers are clear, you have already done much of the work.
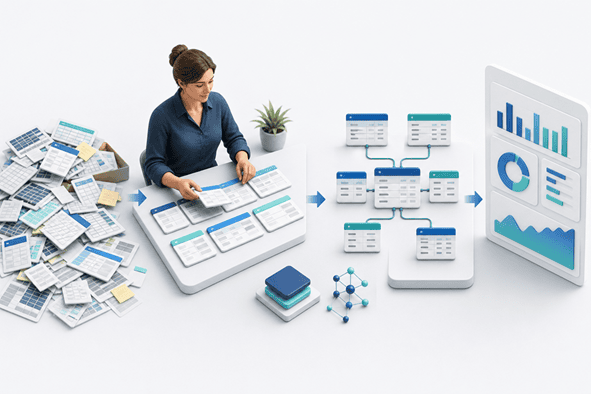
Structure starts with clear rules for rows, columns, identifiers and relationships.
This is part of the pragmatic approach at Datavizin , which starts with a business need, structures the data that matters and builds a solution that fits.
Identify what each row represents
The question seems almost too simple, but it resolves many problems. Does a row represent an order, an order line, an invoice or a customer? If you mix those levels, the same total can be correct in one view and incorrect in another. We ask you to define this in one sentence before any transformation.
A table should describe one type of object or event, such as customers, products, orders, invoices or inventory movements. Mixing levels in a single sheet makes calculations ambiguous.
Ask what exactly one row represents. If the answer varies, split the information into tables linked by an identifier.
Use simple, consistent columns
Each cell should store information the tool can read independently of its colour or position. Keep headings in the report and leave them out of the middle of the data table. Write the entry rules somewhere visible. What seems obvious today may be less clear to the next person.
Each column should hold one piece of information, such as a date, an amount, a code or a category. Avoid merged cells, subtotals within the data and colours that stand in for values.
Standardise date formats, units, yes/no values and categories. A list of allowed values immediately reduces entry errors.
Give columns clear names, use consistent data types and make the entry rules available.
Choose stable identifiers
Labels make information readable. Identifiers link records. A customer can change its company name and a product its trade name without becoming a new object. When joins rely solely on names, we create or restore a stable key before proceeding.
Customer and product names can change. A unique identifier links tables independently of changing labels.
If no identifier exists, create one and document the rule. Row numbers change when you sort or move data, making them unsuitable as identifiers.
Keep raw data, cleaned data and reporting separate
Keeping these stages separate gives you a way to retrace your steps. If a figure surprises you, compare the source you received, the rule you applied and the result you displayed. Without separate stages, people correct the report directly and cannot reproduce the change later.
Keep a copy of the source, apply transformations in a separate step and then feed the report. This improves traceability and makes results reproducible.
When you need to combine several sources or maintain a history, a data mart or database is more reliable than a collection of Excel sheets.
Document before you automate
The documentation can be short. A single page with the definition, source, owner and main check for each critical field is usually enough to start. This modest effort helps you work independently and speeds up later discussions.
Start with a small data dictionary that records names, definitions, sources, formats, owners and quality rules. It keeps key knowledge accessible to everyone.
Datavizin’s ECSTAA method helps you explore systems, understand how data is produced, structure the foundations and then analyse and act.
How we help you take the next step
You can start with the tools you have. Pick a table, write down what one row represents, mark the key and identify the three columns where an error would skew a decision. Then name the person who can validate each rule. This exercise gives us a solid starting point for automation or a more robust data model.
The right next step depends largely on a clearly defined scope, available data and user engagement. A short workshop is often enough to check all three.
| NEXT STEP Explore the ECSTAA model and the Data Strategy Toolkit to structure your data in stages. |